Get in Touch
T: +44 20 3695 9251
E: info@grtconsult.com
71-75 Shelton Street Covent Garden, London, WC2H 9JQ
Get in Touch
T: +44 20 3695 9251
E: info@grtconsult.com
71-75 Shelton Street Covent Garden, London, WC2H 9JQ
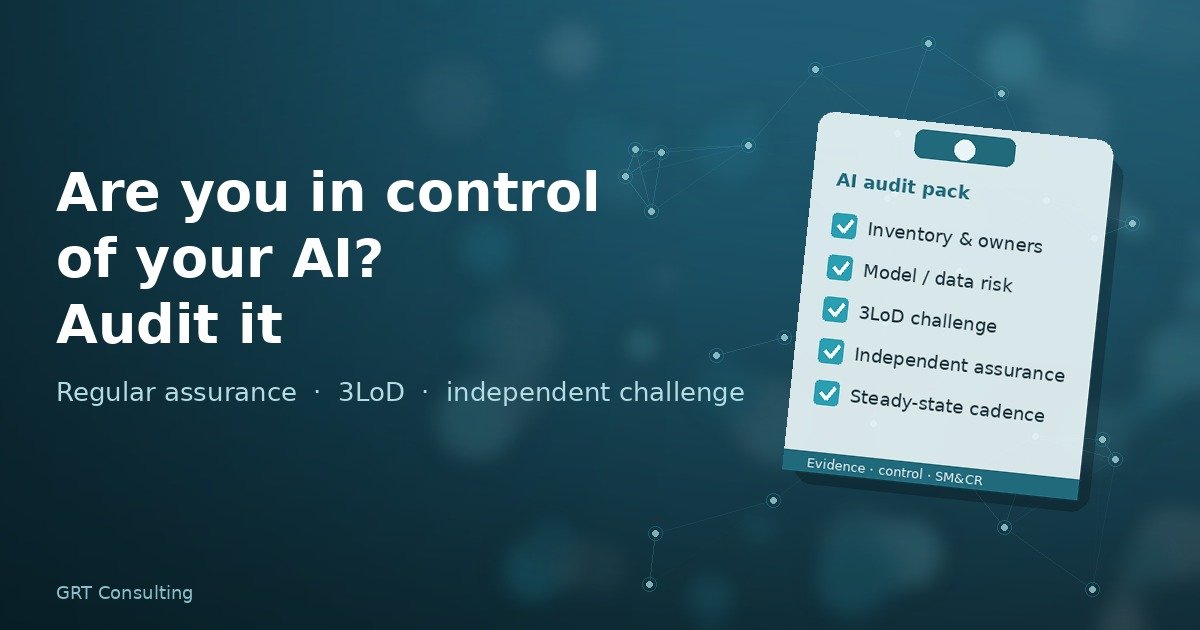
Most firms can point to an AI pilot. Fewer can point to an AI audit file that would survive a senior manager interview.
That gap matters. The FCA’s published position is clear: it does not plan a separate AI rulebook. Existing frameworks — Consumer Duty, SM&CR, SYSC systems and controls, outsourcing and operational resilience — already apply to how you design, buy, run and oversee AI. See AI and the FCA: our approach.
The Mills Review (July 2026) makes the same point for retail finance. As autonomy rises, so does the need for named accountability, continuous assurance, and evidence you can reconstruct after the fact.
So the board question is not “do we have an AI policy?” It is: are you in control?
AI changes after you switch it on. Models drift. Vendors push updates. Staff invent new prompts. Shadow tools appear on phones. A one-off “AI risk assessment” at procurement is not control; it is a snapshot.
Regular audit means a planned cycle that matches how risky and how autonomous the use case is:
| Cadence | Typical use | What you re-check |
|---|---|---|
| Continuous / weekly sampling | Customer-facing agents, credit, advice, payments, financial crime decisions | Outcomes, overrides, incidents, drift alerts, prompt/tool changes |
| Quarterly | Material internal decision support tied to an important business service | Performance vs approval pack, data lineage, access rights, third-party changes |
| Annual (or on material change) | Lower-risk drafting aids with strong human gates | Inventory accuracy, owner attestations, policy fit, retirement candidates |
| Triggered | Any incident, vendor outage, model swap, new data class, new write access | Full re-approval path before scale resumes |
If you cannot say when each live use case was last independently reviewed, you are hoping rather than governing.
Keep the review practical. You are not writing a thesis on neural nets. You are testing whether the firm can defend the outcomes.
| # | Area | Why it sits in the audit file |
|---|---|---|
| 1 | Inventory & shadow AI | You cannot control what you have not listed — including unsanctioned ChatGPT-style tools |
| 2 | Purpose, autonomy & human gates | What the system may do alone vs what a person must approve |
| 3 | Data classes & leakage paths | Customer, market-sensitive, IP and staff data in prompts, logs and vendor stores |
| 4 | Model / vendor change control | Who may update weights, prompts, tools, plugins; how you detect silent changes |
| 5 | Performance, bias & Consumer Duty outcomes | Does it still do what you approved, fairly, for the customers you serve? |
| 6 | Explainability & evidence | Can you reconstruct a decision for a complaint, SAR or SMF interview? |
| 7 | Access, identity & over-privilege | Agents with write access are operational risk, not “IT hygiene” |
| 8 | Resilience & concentration | Same model behind several important business services |
| 9 | Financial crime & conduct misuse | Prompt injection, social engineering, policy invention, unsuitable recommendations |
| 10 | Exit & kill switches | Can you disable a use case or vendor path without taking the firm offline? |
For banks and designated investment firms, the PRA’s SS1/23 model risk management principles remain the cleanest supervisory language for inventory, governance, independent validation and mitigants. That still holds when you stretch the spirit of those principles to generative tools that were not the original use case.
FCA solo firms should not pretend SS1/23 binds them if it does not. They should still recognise the direction of travel.
The PRA’s November 2025 AI/ML model-risk roundtables underline the same themes for dynamic models: more frequent monitoring, quantitative triggers, challenger and fallback options, and kill switches.
You do not need a fourth line called “AI”. Credit, outsourcing and operational resilience already run through first, second and third line. Put AI through the same machinery.
| Line | Job on AI | |
|---|---|---|
| ✓ | First line — business, ops, product | Own the use case: keep it on the inventory, name an owner, write the operating procedures, sample outputs, raise incidents and drill the kill switch |
| ✓ | Second line — risk, compliance, financial crime | Challenge and set the standards: risk tier, policy, Consumer Duty and SM&CR overlays, monitoring thresholds and open-issue tracking |
| ✓ | Third line — internal audit | Give independent assurance: risk-based AI audits across the live inventory, not a one-off “AI project review” and then silence |
AI can help all three lines. It does not replace them. The Mills Review is blunt on that point. Line 1 still owns the outcomes. Line 2 still challenges. Line 3 still reports independent assurance to the board and audit committee.
What usually goes wrong: Line 1 “owns” a vendor chatbot, Line 2 published principles in 2024, and Line 3 has never put AI into the audit universe. That is not three lines of defence. That is a gap with stationery.
Not every use case needs a Big Four model validation army. Materiality does.
Bring in independent / external assurance when:
| Trigger | |
|---|---|
| ✓ | The model or agent can commit the firm — customer communications, pricing, credit, advice, payments or regulatory reporting |
| ✓ | You rely on a third-party foundation model or managed “AI desk” and need audit rights, evaluation evidence and concentration analysis you cannot generate alone |
| ✓ | Internal validation lacks depth on generative systems — prompt injection, tool-use abuse, evaluation harnesses, red-teaming |
| ✓ | The board or audit committee wants an outside view before scale — or after an incident |
Independent work typically covers:
| Scope | |
|---|---|
| ✓ | Inventory completeness and design effectiveness of controls |
| ✓ | Validation of material models and sample testing of outcomes |
| ✓ | Vendor due diligence, contractual audit rights, and whether SM&CR Statements of Responsibilities match who can change the system |
GRT’s view is simple: buy independence where impact is high; build routine assurance where volume is high. Do not pay for theatre on a meeting-summariser, and do not leave a customer-facing agent with a policy PDF as its only control.
Weak AI oversight is not a theoretical “ethics” problem. It shows up as cash, customers and careers.
| Failure mode | What it looks like in practice | Why audit would have helped |
|---|---|---|
| Data leakage | Staff paste code, customer files or meeting notes into consumer AI tools — as reported in the Samsung ChatGPT incidents that led to tighter bans | Inventory, approved tools, DLP, training evidence, sampling of prompts |
| Invented policy / improper usage | A customer-facing bot invents rules the firm never approved — the Air Canada chatbot case made the firm own the output | Scope limits, human gates on commitments, output monitoring vs source of truth |
| Model-led commercial failure | Algorithms that misprice risk at scale — Zillow’s iBuying unwind is the textbook non-FS warning on trusting unchallenged forecasts (coverage) | Independent validation, stress scenarios, kill criteria before capital is committed |
| Change-control / systems failure | Knight Capital’s 2012 trading software incident — material loss and near-failure after a bad release (SEC materials) — still the classic MRM teaching case | Pre-production testing, release controls, kill switches, independent challenge |
| Cyber attack surface | Prompt injection, over-privileged agents, poisoned context, AI-accelerated social engineering | Identity controls, tool permissions, red-team tests, incident playbooks that include “disable the agent fleet” |
| Shadow AI & IP loss | Unmonitored tools become the real operating model; know-how walks into a vendor log | Discovery scans, approved alternatives, attestation |
| Bias / unfair outcomes | Credit, pricing or servicing models that treat customers unevenly under Consumer Duty | Fairness testing, outcome MI, challenge by Line 2 |
| Correlated / concentration failure | Many teams on one model or one cloud LLM — one outage or one bad update hits several important business services | Resilience mapping, exit plans, diversification where needed |
| Accountability vacuum | “The model did it” meets SM&CR — no SMF can show reasonable steps | Named owners, change logs, reconstruction packs |
Regulators will not invent a new excuse for you. They will ask who owned it, what it was allowed to do, what it did, how you spotted it, and what you changed.
Answer these without a slide deck:
If any answer is “not really”, you are not in control. You are in production.
Good in 2026 is boring on purpose:
| What good looks like | |
|---|---|
| ✓ | A living inventory with risk tiers and SMF / business owners |
| ✓ | Human gates written into workflows, not into posters |
| ✓ | Monitoring that produces exceptions humans actually clear |
| ✓ | Line 3 coverage in the audit plan, themed across AI — not a one-off project review |
| ✓ | Vendor AI treated as outsourcing / third-party risk where it is material |
| ✓ | Board / audit committee MI that shows inventory growth, incidents, overdue validations and kill-switch tests — not “number of AI ideas” |
| ✓ | Evidence packs that a reasonable SMF would be willing to sit behind |
| ✓ | Optional structure from NIST AI RMF or ISO/IEC 42001 — useful scaffolding, not a substitute for FCA/PRA outcomes |
That is enough to scale the uses that deserve scale — and to stop the ones that do not.
<!–CHEVRON–>
| Stage | Outcome |
|---|---|
| 1. Inventory & classify | Complete list of AI uses, data classes, autonomy, customer impact |
| 2. Risk tier & owners | Every material case has a business owner and a challenger |
| 3. Controls & testing | Gates, logging, evaluation harness, change control designed in |
| 4. 1LoD / 2LoD assurance | Operating sampling + independent challenge with open-issue tracking |
| 5. Independent validation | External or truly independent review where impact warrants it |
| 6. Continuous monitor | Drift, incidents, vendor changes, outcome MI on a fixed rhythm |
| 7. Steady-state audit cycle | Line 3 plan, board reporting, refresh on triggers — then repeat |
Skip stages and you get theatre. Finish stage 7 and AI stops being a special project. It becomes another controlled capability.
GRT works with operational, risk, compliance and internal audit teams who need AI that survives contact with FCA expectations — not another principles PDF.
We help firms:
| How we help | |
|---|---|
| ✓ | Shape an AI audit and assurance strategy that fits your permissions, not a generic tech maturity model |
| ✓ | Build the inventory, tiering and owner map so SM&CR lines up with reality |
| ✓ | Design 1LoD / 2LoD operating rhythms and Line 3 scopes that cover generative and agentic use cases |
| ✓ | Stand up practical controls — human gates, observability, evaluation, kill switches, third-party overlays |
| ✓ | Bring independent challenge on material models and vendor AI where you need an outside view |
| ✓ | Train teams to supervise agents so productivity gains do not outrun control |
If you want a structured conversation about whether you are actually in control of your AI — and what to fix first — talk to us.
T: +44 20 3695 9251 E: info@grtconsult.com Web: grtconsult.com
Sources